Cross-Attention in Encoder-Decoder Transformers: How LLMs Condition Outputs
- Mark Chomiczewski
- 6 September 2026
- 10 Comments
You have probably heard of the Transformer architecture. You might even know that it relies on self-attention to let words look at each other within a single sentence. But here is the catch: if you are building a translation model or a chatbot that needs to read a document and then answer questions about it, self-attention alone isn't enough. The model needs a way to bridge two different sequences. It needs to connect the input (the source) with the output (the target). This is where cross-attention comes in.
Think of it this way. In a standard decoder-only model like GPT, the model only looks backward at what it has already generated. It doesn't have a separate "input" stream to reference after the initial prompt. But in an encoder-decoder setup, like T5 or BART, the encoder processes the input once, and the decoder generates the output token by token. The decoder needs a direct line of communication to the encoder's understanding of the source text. That line is cross-attention.
What Exactly Is Cross-Attention?
Cross-attention is a specialized attention mechanism in transformer architectures that allows a decoder layer to attend to key-value pairs derived from an encoder's output. Unlike self-attention, where queries, keys, and values all come from the same sequence, cross-attention splits these roles across two different sources.
In simple terms, the decoder asks questions (queries), and the encoder provides the answers (keys and values). When the decoder wants to generate the next word in a translation, it doesn't just guess based on previous words. It looks back at the original sentence processed by the encoder. It checks which parts of the source sentence are most relevant to the current step of generation.
This mechanism is critical for tasks where the output depends heavily on specific details in the input. Machine translation is the classic example. If you are translating "The cat sat on the mat," the decoder needs to know exactly where "cat," "sat," and "mat" were located in the source language to produce the correct grammar in the target language. Cross-attention provides that spatial alignment.
The Mechanics: Queries, Keys, and Values
To understand how this works under the hood, we need to look at the three main components of any attention mechanism: Query (Q), Key (K), and Value (V). In self-attention, Q, K, and V are all projections of the same input sequence. In cross-attention, they come from different places.
- Query (Q): Generated from the current state of the decoder. This represents what the model is trying to predict right now.
- Key (K): Generated from the output of the encoder. These represent the positions in the source sequence.
- Value (V): Also generated from the encoder. These contain the actual information content associated with those positions.
The math follows the standard scaled dot-product attention formula, but the inputs are asymmetric. The model computes the similarity between the decoder's query and the encoder's keys. High similarity scores mean the decoder should pay close attention to that specific part of the source text. These scores are normalized using softmax to create a probability distribution. Finally, the model uses these probabilities to weight the encoder's value vectors, creating a context vector that informs the next prediction.
| Feature | Self-Attention | Cross-Attention |
|---|---|---|
| Source of Query (Q) | Current Layer Input (Decoder or Encoder) | Decoder State |
| Source of Key (K) | Current Layer Input (Same as Q) | Encoder Output |
| Source of Value (V) | Current Layer Input (Same as Q) | Encoder Output |
| Primary Use Case | Understanding context within one sequence | Aligning input sequence to output sequence |
| Location in Architecture | Both Encoder and Decoder layers | Only in Decoder layers |
Why Decoders Need Conditioning
You might ask, why not just feed the encoder's final output into the decoder? Why do we need attention at every layer?
Because a single fixed vector cannot capture everything. Imagine translating a long paragraph. The encoder compresses the entire paragraph into a set of contextualized embeddings. If the decoder had to rely on just one summary vector, it would lose detail. It wouldn't know if the subject was singular or plural, or which verb tense to use, because that information is diluted across the whole sequence.
Cross-attention solves this by allowing dynamic conditioning. At each step of generation, the decoder can "look up" specific information. If the decoder is generating the word "ran," it attends to the past-tense markers in the encoder's output. If it is generating "run," it looks elsewhere. This dynamic retrieval ensures that the output remains faithful to the input, no matter how complex or long the source text is.
This process happens in every decoder layer. The first layer might handle basic word alignments. Deeper layers might handle syntactic structures or semantic nuances. By stacking these layers, the model builds a sophisticated understanding of the relationship between the input and output sequences.
Beyond Translation: Multimodal Applications
While machine translation made cross-attention famous, its utility extends far beyond language-to-language tasks. Today, cross-attention is the backbone of many multimodal AI systems.
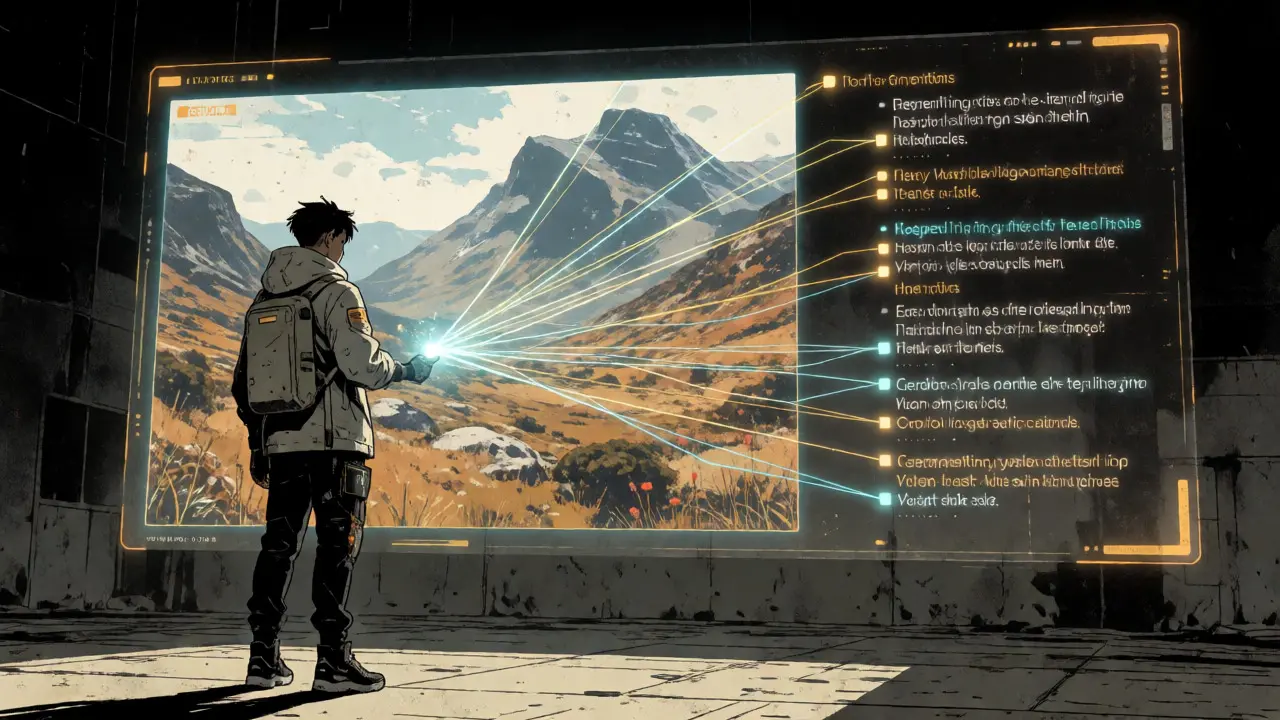
Consider image captioning. Here, the encoder is often a Vision Transformer (ViT) that processes an image into a sequence of patches. The decoder is a language model that generates text. The decoder uses cross-attention to look at the image patches. When it generates the word "sky," it attends to the upper regions of the image. When it generates "grass," it attends to the lower regions. The mechanism is identical to translation; only the data types differ.
This flexibility makes cross-attention essential for modern large language models (LLMs) that handle multiple modalities. Whether you are dealing with audio, video, or code, if there is a distinct input stream that needs to inform an output stream, cross-attention is likely the tool being used.
Implementation Details and Pitfalls
If you are implementing this yourself or debugging a model, there are a few technical details to keep in mind.
First, masking is crucial. Encoders often pad shorter sequences to match batch sizes. The decoder must ignore these padding tokens during cross-attention. If it doesn't, the model will waste attention capacity on empty space. This is handled by applying an encoder padding mask to the attention scores before the softmax operation. Any position corresponding to padding gets a score of negative infinity, effectively zeroing out its influence.
Second, initialization matters. The projection matrices for W_Q, W_K, and W_V need proper initialization to ensure stable gradients. Poor initialization can lead to vanishing or exploding gradients, especially in deep networks. Standard practices like Xavier or He initialization are typically sufficient, but care must be taken to scale them appropriately for the dimensions of the hidden states.
Third, computational cost. Cross-attention adds overhead. For every decoder layer, you are computing attention over the entire length of the encoder output. If your input sequences are very long, this can become a bottleneck. Recent research focuses on sparse attention patterns or linear attention approximations to mitigate this cost, but standard dense cross-attention remains the default for most high-performance models.
When Do You Actually Need It?
Not every model needs cross-attention. If you are fine-tuning a GPT-style model for summarization, you don't use it. Those models are decoder-only. They treat the input as part of the context window and generate the rest. There is no separate encoder pathway.
You need cross-attention when:
- You are using an encoder-decoder architecture (like T5, BART, or MarianMT).
- You are building a multimodal system where one modality conditions another (e.g., vision-to-text).
- You want explicit separation between processing input and generating output.
For pure generative tasks where the input is short relative to the output, or where the model can simply prepend the input to the sequence, decoder-only models are often simpler and faster. But for tasks requiring precise alignment between two distinct sequences, cross-attention is non-negotiable.
What is the difference between self-attention and cross-attention?
Self-attention allows a sequence to attend to itself, relating positions within the same input or output stream. Cross-attention allows one sequence (usually the decoder) to attend to a different sequence (usually the encoder). Self-attention is used in both encoders and decoders, while cross-attention is exclusively found in decoders of encoder-decoder architectures.
Do all Large Language Models use cross-attention?
No. Most popular open-source LLMs like Llama, Mistral, and GPT variants are decoder-only models. They use causal self-attention and do not have a separate encoder component, so they do not use cross-attention. Models like T5, BART, and Flan-T5 are encoder-decoder models and do use cross-attention.
How does cross-attention help in machine translation?
It enables the decoder to align the target language output with the source language input. By attending to specific positions in the encoded source sentence, the decoder can ensure grammatical correctness and semantic fidelity, effectively "looking back" at the original text while generating the translation.
Can cross-attention be used for image generation?
Yes. In diffusion models or autoregressive image generators, cross-attention is often used to condition the image generation process on a text prompt. The text prompt is encoded, and the image decoder attends to these text embeddings to guide the visual features being created.
Is cross-attention computationally expensive?
It can be. The complexity is proportional to the product of the decoder sequence length and the encoder sequence length. For very long inputs, this can be costly. However, optimizations like flash-attention and sparse attention mechanisms help reduce this overhead significantly in practice.
Comments
Sabrina Newland
its wild how much we take for granted that models can just "see" the connection between two totally different things 🤯 like its almost philosophical in a way... are they truly understanding or just mirroring patterns? 🧠✨ i love thinking about this stuff
September 6, 2026 AT 23:46
Art HND
Overcomplicated explanation for a simple matrix multiplication. Decoder-only works fine.
September 8, 2026 AT 11:26
Elizabeth Brooks
actually decoder only struggles with long context alignment sometimes
cross attn is cleaner for seq2seq tasks imo
September 10, 2026 AT 05:46
Mark Harvey
totally agree elizabeth and hey everyone keep experimenting dont let the complexity scare you off its all about iteration and learning from mistakes you got this
September 10, 2026 AT 07:08
Deb Kortyna, MBA
It is absolutely paramount to recognize that without cross-attention, multimodal systems would essentially collapse into chaos. The elegance of the mechanism cannot be overstated; it provides the necessary structural integrity for coherent output generation. One must appreciate the sophistication involved here.
September 10, 2026 AT 17:41
Quintin Franzese
oh wow another tech post explaining something everyone already knows but using ten times more words than necessary brilliant really groundbreaking stuff here folks 👏
September 11, 2026 AT 18:34
Amara Akbar
I believe that recognizing the distinct roles of queries and keys is a crucial step in mastering transformer architectures. It is wonderful to see such clear distinctions being made so that learners can feel confident in their understanding. You are doing great work by clarifying these concepts.
September 13, 2026 AT 16:04
Brandon Olvera
america built the first transformers and we still lead in optimization while europe plays around with theory get real
September 14, 2026 AT 16:00
alex kobri
there is a deeper question here about whether attention implies consciousness or if its just math pretending to be thought
i think its the latter but maybe im wrong
September 15, 2026 AT 02:29
Zach Loescher
interesting point about masking though i wonder how much that actually impacts performance on very short sequences vs long ones feels like it might be negligible for short inputs
September 16, 2026 AT 21:10