Prompt Management in IDEs: Best Ways to Feed Context to AI Agents
- Mark Chomiczewski
- 21 August 2026
- 7 Comments
You know that feeling when your AI coding assistant is a tool that helps write and debug code but often misses the specific nuances of your project structure? You type a clear request, but the output feels generic. It ignores the framework version you're using or forgets the helper function you defined three files ago. This isn't a model intelligence problem; it's a context delivery problem.
In 2026, the race isn't about who has the biggest language model. It's about who can feed the right information at the right time without bloating the token count. Effective Prompt Management in IDEs is the systematic approach to structuring and delivering contextual data to AI agents to maximize relevance while minimizing cost. Whether you use Visual Studio Code, JetBrains IDEs, or Amazon Q Developer, mastering how your environment captures and prioritizes context is the single biggest lever for productivity.
Why Context Quality Beats Quantity
Many developers fall into the trap of thinking "more context equals better answers." They dump entire folders into the chat window, hoping the AI will find the needle. But as Dr. Elena Rodriguez from Lakera AI pointed out in her 2025 guide, the top 10% of developers don't feed more context-they feed better context. When you overload an agent with irrelevant files, you introduce noise. The model gets confused by conflicting patterns, leading to what users call "context drift," where the AI slowly loses track of the task after 15-20 minutes of continuous work.
The goal is precision. You want the AI to see the current file, the specific dependencies it relies on, and the constraints of your runtime environment. That's it. If you're fixing a bug in a Python service, the AI doesn't need to know about the CSS styles in your frontend repository. It needs to know the exact version of Django you're running and the database schema related to that specific endpoint. Focusing on high-signal data reduces hallucinations and keeps the AI aligned with your actual codebase.
The Three Layers of Context Architecture
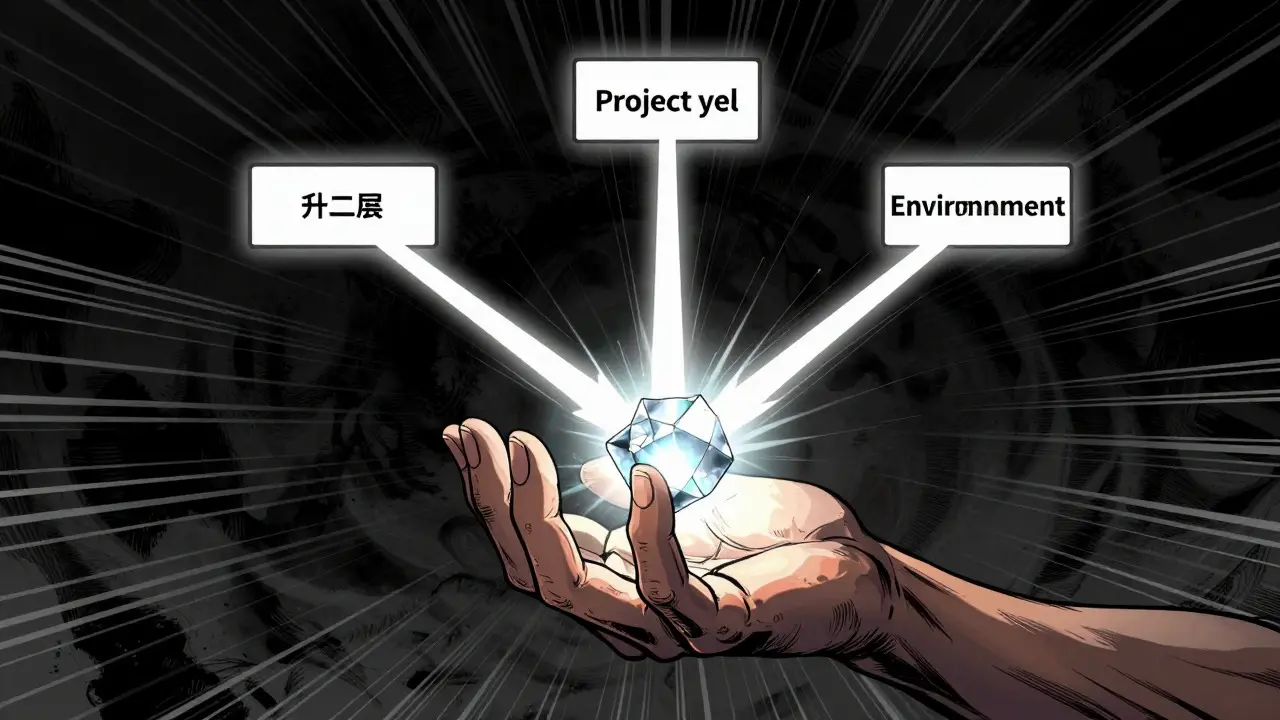
To manage this effectively, you need to understand the multi-layered context architecture used by modern IDEs. Most sophisticated systems, like JetBrains AI Assistant, which reached version 2.3 in late 2025, operate on three distinct layers:
- File-Level Context: This includes the content of the file you are currently editing, your cursor position, and any selected text. This is the highest-priority layer. If you highlight a function, the AI should treat that snippet as the primary subject of its response.
- Project-Level Context: This covers related files, import statements, and architectural patterns. For example, if you edit a controller, the AI should automatically consider the corresponding model and view files. Systems like GitHub Copilot Chat use semantic similarity to guess these relationships, achieving around 82% relevance accuracy in recent benchmarks.
- Environment Context: This is often overlooked but critical. It includes framework versions, system configuration, and runtime constraints. Knowing whether you are using Node.js 18 or 20 changes the available APIs significantly. Without this layer, the AI might suggest deprecated methods or incompatible syntax.
Understanding these layers helps you diagnose why an answer failed. Did the AI miss the file-level selection? Or did it ignore the environment constraint? Identifying the missing layer allows you to manually inject the correct context.
Comparing Major IDE Approaches
Different IDE vendors handle context management differently. Your choice of tool dictates your workflow. Here is how the major players stack up in 2026:
| IDE Platform | Primary Strategy | Key Feature | Accuracy/Impact Metric |
|---|---|---|---|
| Visual Studio Code | Automatic Semantic Selection | Copilot Chat Context Window | 82% relevance accuracy (GitHub Internal Metrics) |
| JetBrains IDEs | Explicit Context Pinning | Manual File Designation & Weighted System | 33% fewer context-related errors (User Survey) |
| Amazon Q Developer | Context Graph Mapping | Relationship Mapping Between Code Elements | 41% improvement in cross-file understanding (AWS Testing) |
| Continue.dev | Customizable Templates | YAML-Based Project Rules | 68% of adopters report improved effectiveness |
Notice the trade-off. VS Code offers a seamless, "set it and forget it" experience, but it can suffer from context drift during long sessions. JetBrains gives you control through explicit pinning, which requires more upfront effort but yields higher consistency for complex refactoring. Amazon takes a structural approach, mapping how functions call each other, which is excellent for large monoliths. Continue.dev appeals to those who want full transparency and customization via YAML files.
Practical Techniques for Better Prompts
Knowing the architecture is one thing; applying it is another. Here are four concrete techniques to improve your daily workflow immediately.
- Use Explicit Constraints Early: According to Google's Gemini API documentation, essential constraints should be placed at the very beginning of the prompt. If you need the output in TypeScript, say so first. If you need to avoid external libraries, state that before asking for the solution. This anchors the model's behavior before it starts generating code.
- Leverage "Leading Words": For code-specific tasks, start your prompt with keywords that trigger the correct pattern. In Python, starting with "import" or "def" guides the model toward standard library usage. In SQL, starting with "SELECT" ensures a query structure. These small cues reduce ambiguity significantly.
- Adopt Plan-Then-Act Workflows: JetBrains recommends a two-step process. First, ask the AI to outline the approach in "Plan Mode" without writing code. Review the plan. Then, switch to "Act Mode" to execute. This prevents cascading errors where a wrong initial assumption ruins the entire implementation.
- Create Task-Specific Templates: Don't use one generic prompt for everything. Create templates for bug fixing, feature development, and documentation. A bug-fixing template might explicitly ask for root cause analysis, while a feature template asks for edge case handling. Top performers in recent surveys use at least three specialized templates.
Managing Token Limits and Caching
Context isn't free. Every token you send costs money and consumes time. Modern AI agents rely on prompt caching to speed up responses. If you change the beginning of your prompt, you invalidate the cache, forcing the model to reprocess everything. This makes iterative refinement slow and expensive.
To mitigate this, build your prompts so they are appended to during a session rather than rewritten. Keep your core context stable. If you need to add new information, add it at the end. As Alex Chen from Augment Code noted, maintaining a stable prefix allows the system to reuse cached computations, reducing latency by up to 40% in repeated interactions. This is particularly important for enterprise environments where response time impacts developer flow state.
The Future: Self-Optimizing Context
We are currently in the era of manual curation, but the next frontier is automation. Gartner forecasts that by 2027, 65% of enterprise IDEs will include self-optimizing context management. Imagine an AI agent that analyzes the complexity of your task and automatically determines the optimal context parameters. If you are doing a simple variable rename, it minimizes context to save tokens. If you are refactoring a microservice, it expands context to include all dependent services.
Until then, the power lies in your hands. By understanding how your IDE captures context, you stop fighting the tool and start guiding it. The developers who thrive in 2026 aren't just good coders; they are effective communicators who know exactly what their AI agent needs to hear.
What is the best way to fix context drift in AI coding assistants?
Context drift occurs when the AI loses focus during long sessions. To fix this, use explicit context pinning features available in IDEs like JetBrains to lock in critical files. Alternatively, restart the conversation with a concise summary of the current state and the immediate goal. Avoid letting the conversation history grow too long without resetting the focus.
Should I always include the entire project folder in my prompt?
No. Including the entire project folder usually introduces noise and increases token costs without improving accuracy. Instead, rely on the IDE's automatic semantic selection or manually pin only the files directly relevant to the task. Focus on the specific module or component you are working on, along with its direct dependencies.
How does prompt caching affect my workflow?
Prompt caching speeds up responses by reusing previously processed context. To benefit from this, keep the beginning of your prompt consistent across multiple requests. Append new instructions at the end rather than rewriting the entire prompt. This maintains the cache validity and reduces both latency and API costs.
Which IDE has the best context management for large codebases?
For large, complex codebases, JetBrains IDEs and Amazon Q Developer tend to perform well due to their structured approaches. JetBrains allows explicit control over which files are included, reducing errors. Amazon uses a context graph to map relationships between code elements, improving cross-file understanding. Choose based on whether you prefer manual control or automated relationship mapping.
Do I need to learn prompt engineering separately from coding?
Not necessarily. While deep prompt engineering skills help, most benefits come from understanding basic principles like clarity, specificity, and context layering. You don't need to master advanced techniques for every task. Start with simple, structured prompts and refine them based on feedback. The key is treating the AI as a junior developer who needs clear instructions and relevant examples.
Comments
Anthony Miller
YOU ARE ALL WASTING YOUR TIME ON THIS
THE REAL ISSUE IS THAT THE IDE VENDORS WANT YOU TO BELIEVE THAT CONTEXT MANAGEMENT IS A FEATURE RATHER THAN A FUNDAMENTAL FLAW IN THEIR ARCHITECTURE
IF YOU HAVE TO MANUALLY PIN FILES OR WRITE YAML CONFIGS THEN THE TOOL IS NOT SMART ENOUGH TO DO IT FOR YOU
I HAVE BEEN USING JETBRAINS FOR YEARS AND I CAN TELL YOU THAT THE 'EXPLICIT CONTEXT PINNING' IS JUST A EUPHEMISM FOR MANUAL LABOR
STOP BLAMING THE MODEL AND START BLAMING THE ENGINEERING DEPARTMENT THAT BUILT A SYSTEM THAT REQUIRES HUMAN INTERVENTION TO BE USEFUL
THIS POST IS A BAND-AID ON A GUNSHOT WOUND
August 22, 2026 AT 12:17
Savara Gunn
He makes a fair point about the manual labor aspect, though I think it depends on how much control you want. For me, the explicit pinning in JetBrains is actually a relief because I hate when the AI guesses wrong and I have to explain why it was wrong. It feels more like working with a junior dev who needs clear instructions rather than an oracle that should just know everything. The trade-off is worth it for complex refactors.
August 23, 2026 AT 15:13
Tamara Miller
Oh, wonderful, another article telling us that we are doing it wrong.
You know what? It's not our fault the AI is dumb, it's their fault for building a dumb tool.
And don't get me started on this 'context drift' nonsense; that's just a fancy way of saying the conversation got too long and the machine forgot what it was doing.
Why do we need 'layers'? Why can't it just read the code?
I bet if they charged us less per token, we wouldn't care so much about optimizing every single character.
It's all just marketing speak to make us feel productive while we're actually just babysitting a robot.
But sure, keep your YAML files, they look very professional on a resume.
August 24, 2026 AT 05:42
michelle veluz
Wait, did anyone else notice that Amazon Q is basically just spying on our code structure now??
'Context Graph Mapping' sounds exactly like corporate surveillance to me!
They are mapping our dependencies to sell data back to us or to figure out which companies to acquire next!!
It's not about 'cross-file understanding', it's about cross-company intelligence gathering!!!
Stick with VS Code, at least GitHub is transparent about being owned by Microsoft (which is also bad, but at least we know the enemy!).
These big tech companies are always one step ahead of us, hiding their motives behind 'productivity' metrics.
Be careful what you feed the machine, it might be feeding them right back!
August 25, 2026 AT 11:21
Jacob Baby Official
Actually, the entire premise of this post is flawed. If you have to manage context, you aren't coding, you're prompting. And if you're prompting, you've already lost the flow state. The best IDEs are the ones where you forget the AI exists. By highlighting these 'techniques', you are admitting that the current generation of tools are fundamentally broken and require constant human micromanagement to function. It's not a workflow improvement, it's a workaround for poor engineering. Stop celebrating the hack and start demanding the fix.
August 27, 2026 AT 10:21
john randall
Fair point. I mostly use Continue.dev because I like seeing exactly what is being sent. The YAML stuff is a bit of a setup cost but once it's there, it's pretty set-and-forget. Doesn't feel like micromanagement to me, more like configuring my environment once.
August 27, 2026 AT 15:19
Jeff Falcon
I mean, I guess it depends on the project size, right? Like, if you're working on a small script, yeah, maybe you don't need all that heavy lifting, but for a massive monolith, having those templates really does save time, especially when you're dealing with legacy code that has no documentation, which, let's be honest, most of us are, so having a structured way to tell the AI what matters is kind of essential, otherwise you end up with generic answers that don't fit your specific stack, which is frustrating, but at least now we have some vocabulary for it, like 'context drift' and 'semantic selection', which helps when talking to other devs about why the bot gave a bad answer.
August 28, 2026 AT 05:46