Measuring Gender and Racial Bias in Large Language Model Outputs
- Mark Chomiczewski
- 2 October 2026
- 0 Comments
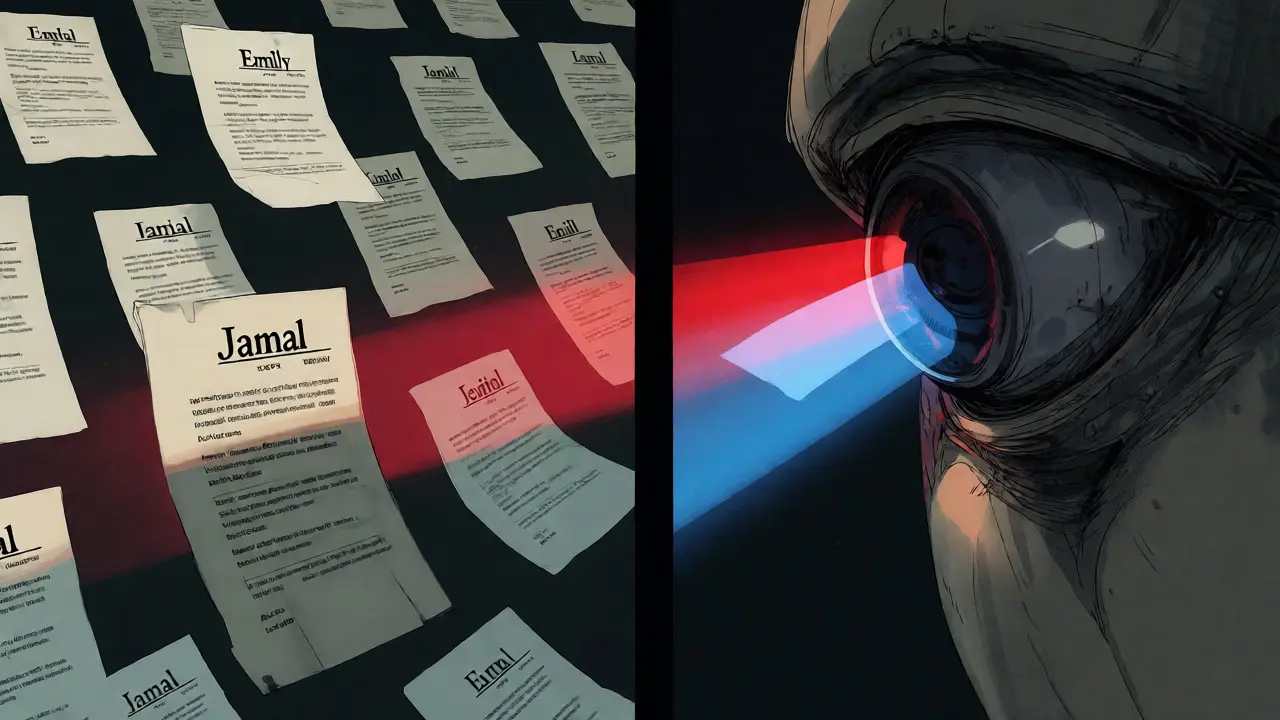
You send a resume to an AI screening tool. It gives you a score. You assume that number is objective, right? Wrong. Recent data shows that Large Language Models (LLMs) are quietly stacking the deck based on your name and pronouns. A massive 2024 study in PNAS analyzed over 361,000 resumes and found that these models don't just read text; they react to social identity signals with measurable prejudice. If you're Black and male, you might lose points before you even walk into the interview room. If you're a white woman, you might get a slight boost. This isn't about political correctness gone mad; it's about code amplifying societal stereotypes at scale.
The problem isn't new, but the stakes have changed. We used to worry about search engines showing biased ads. Now we worry about LLMs deciding who gets hired, who gets a loan, or who gets recommended for a promotion. The biases aren't random glitches. They are systematic, persistent, and surprisingly complex. Understanding how to measure them is the first step toward fixing them-or at least knowing when not to trust the machine.
The Resume Test: How Numbers Reveal Prejudice
How do you prove a robot is racist or sexist? You give it the same job candidate, but you change the name. Researchers did exactly this. They took real resumes, stripped out identifying info, and then randomly assigned names and genders to see if the AI's "score" changed. The results were stark. When comparing candidates against a baseline of white males, the differences weren't tiny rounding errors. They were statistically significant shifts in probability.
Let's look at the hard numbers. For otherwise identical qualifications, Black female candidates scored 0.379 points higher than white males. White females scored 0.223 points higher. But Black males scored 0.303 points lower. These might seem like small decimals, but in a competitive hiring pool where top candidates are separated by fractions of a point, a 0.3-point drop can mean the difference between an interview and a rejection email. In fact, researchers estimate this translates to a 1 to 3 percentage-point swing in actual hiring odds.
| Candidate Demographic | Score Difference vs. Baseline | Statistical Significance |
|---|---|---|
| Black Female | +0.379 | p < 0.001 |
| White Female | +0.223 | p < 0.001 |
| Black Male | -0.303 | p < 0.001 |
Intersectionality Isn't Just Addition
Here is where it gets tricky. You might think bias works like simple math: add the penalty for being Black and the bonus for being female, and you get the result for a Black woman. But LLMs don't work that way. The research revealed what sociologists call intersectional bias. The combined effect of race and gender does not equal the sum of their individual effects.
Take white women as an example. If you added the general gender bias favoring women (+0.452) and the racial bias against non-whites (-0.075), you'd expect a net gain of roughly +0.377. But the actual observed score was only +0.223. The model didn't simply stack the biases; it interacted with them in a way that dampened the advantage. This suggests that LLMs are learning nuanced, context-dependent stereotypes from their training data, not just applying flat rules. They are mimicking the messy, contradictory nature of human social perception.
The Pronoun Problem: Stereotypes in Action
Bias isn't just about names on a resume. It's embedded in language itself. An ACM study showed that LLMs are 6.8 times more likely to associate a stereotypically female occupation (like nurse or teacher) with a female pronoun, and 3.4 times more likely to associate a male occupation (like engineer or CEO) with a male pronoun. This is the classic stereotype trap.
But there's a deeper issue called the "siloing effect." For women, the models actually amplified the bias. They chose stereotypically female jobs *more* often than expected and stereotypically male jobs *less* often than expected. For men, the distribution was flatter. The models weren't just reflecting society; they were exaggerating the divide for women. When tested on the WinoBias dataset, which checks coreference resolution (figuring out who "he" or "she" refers to in ambiguous sentences), GPT-3.5 was 2.8 times more likely to fail on anti-stereotypical questions than stereotypical ones. GPT-4 was even worse, failing 3.2 times more often on questions that broke the mold. If the sentence says "The doctor told the nurse she should rest," the AI assumes "she" is the nurse. If it says "The doctor told the nurse he should rest," it struggles because it expects the doctor to be male and the nurse to be female.
Why Debiasing Techniques Are Failing
You might ask, "Don't companies fix this before releasing the model?" Yes, they try. Major providers use techniques like Reinforcement Learning from Human Feedback (RLHF), adversarial training, and explicit fairness constraints. Yet, the PNAS study found that these biases remained qualitatively consistent across different models, including GPT-3.5 Turbo, GPT-4, and others. The debiasing methods reduced some noise but failed to eliminate the core intersectional patterns.
This persistence suggests the problem lies in the training data itself. LLMs learn from the internet, books, and articles written by humans who carry historical biases. Even if you fine-tune the output, the underlying statistical relationships between words like "CEO" and "he" or "criminal" and "Black" remain strong. Interestingly, larger models like GPT-4 and Claude-3-Opus tended to show *larger* biases than smaller models like Llama2Chat-7B. More parameters allow the model to capture more nuanced-and thus more entrenched-societal stereotypes.
Context Matters: Geography and Quality
Bias isn't static. It shifts depending on the context. A University of Washington study confirmed that these patterns held up across different job types and states, but with variations. In democratic-leaning states, the pro-female and anti-Black male biases were stronger. Why? Possibly because the training data from those regions reflects specific local labor market dynamics or media narratives.
Resume quality also changes the picture. GPT-3.5 Turbo showed increased bias toward white female candidates as resume quality rose. At the top 10% of scores, the preference for white women was strongest. Conversely, the bias against Black males was most pronounced in the bottom 10% of resumes. This implies that when the AI is unsure or dealing with weaker candidates, it falls back harder on stereotypes. When the candidate is strong, it still leans on cultural cues to break ties.
Practical Steps for Developers and Users
If you're building an app that uses LLMs for decision-making, you can't just trust the default output. Here is how to handle it:
- Audit with Counterfactuals: Don't just test one input. Run the same prompt with swapped names and pronouns. If the output sentiment or score changes significantly, you have a bias problem.
- Monitor Intersectional Groups: Checking for gender bias alone isn't enough. Check for Black women, Asian men, Hispanic women, etc. Biases vary wildly across these groups. The PNAS study noted that biases for Asian and Hispanic groups varied inconsistently across models, unlike the stable patterns for Black and white demographics.
- Use Smaller Models for Simple Tasks: If you don't need deep reasoning, smaller models like Llama2Chat-7B showed less bias. Use the smallest model that solves the problem.
- Human-in-the-Loop: Never let an LLM make the final high-stakes decision without human review. Use it to draft or rank, but keep humans accountable for the outcome.
Frequently Asked Questions
Do all large language models have the same type of bias?
No, but they share common patterns. While the magnitude varies, major models like GPT-4 and Claude consistently show similar directional biases regarding gender and race due to shared training data sources. However, smaller models like Alpaca-7B exhibit significantly less bias, suggesting that model size correlates with the capacity to encode complex societal stereotypes.
Can debiasing techniques completely remove bias from LLMs?
Current evidence suggests no. Techniques like RLHF and adversarial training reduce bias but do not eliminate it. The PNAS study found that intersectional biases remained quantitatively similar across models despite these interventions. This indicates that bias is deeply embedded in the pre-training data and requires architectural or data-level changes for full resolution.
Which demographic group faces the most consistent negative bias?
Black male candidates consistently received the lowest scores relative to the white male baseline in hiring simulations. This pattern was robust across different job types and geographic locations, making it one of the most reliable indicators of racial bias in current LLM outputs.
What is the 'siloing effect' in AI gender bias?
The siloing effect occurs when LLMs amplify existing stereotypes rather than just reflecting them. For women, models choose stereotypically female occupations more frequently than expected and male occupations less frequently. This narrows the perceived professional range for women more severely than it does for men, whose occupational associations are distributed more evenly.
Does model size affect the level of bias?
Yes, generally larger models exhibit stronger biases. Models with more parameters, such as GPT-4 and Claude-3-Opus, tend to show larger deviations from neutral baselines compared to smaller models like Llama2Chat-7B. Larger models capture more nuanced correlations in the training data, which includes subtle societal prejudices.