Toolformer-Style Prompts: Teaching LLMs to Call Tools and APIs
- Mark Chomiczewski
- 17 October 2026
- 0 Comments
You ask a large language model for the current price of Bitcoin. It guesses based on its training data, which is outdated. You need it to check an API. But how do you make the model realize it doesn't know the answer and needs to fetch it? This is where Toolformer comes in. It’s not just a paper from Meta AI; it’s the blueprint for how modern agents decide when to stop talking and start acting.
What Toolformer Actually Does
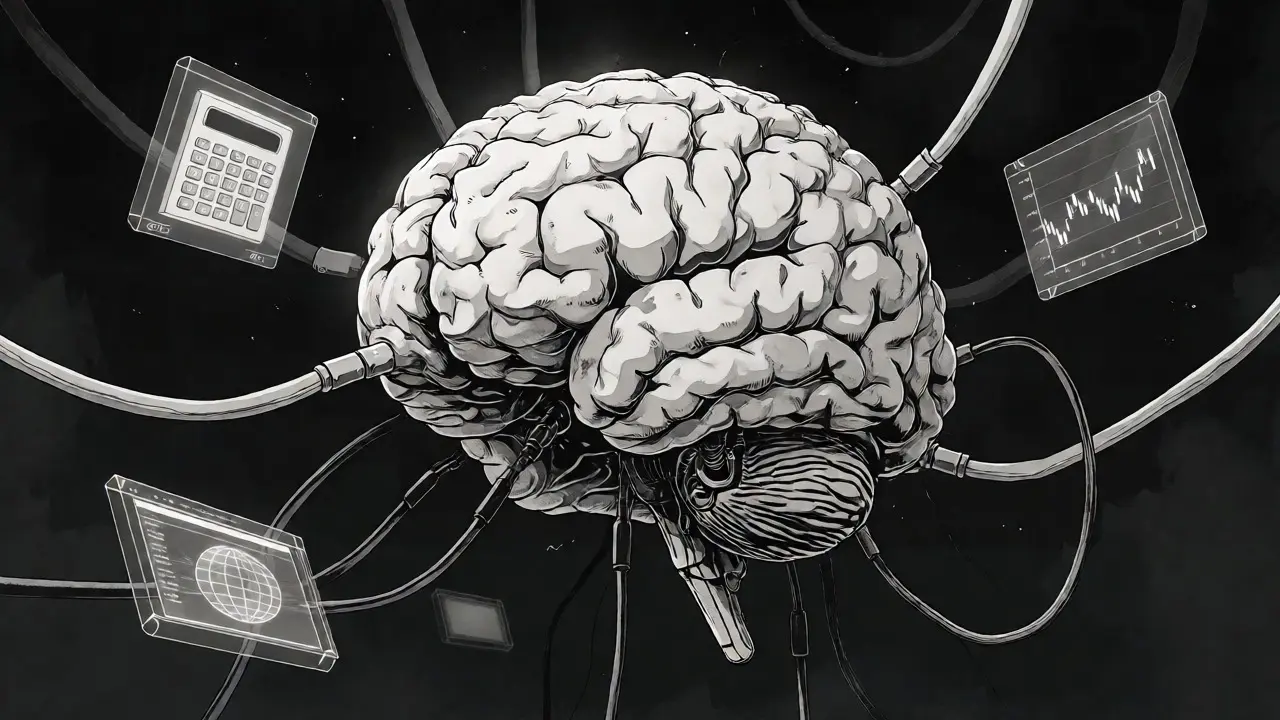
Think of standard LLMs as brains in a jar. They have vast knowledge but no hands. They can’t open a browser or run a calculation unless you explicitly tell them to step-by-step. Toolformer changes this by teaching the model to insert special tokens into its own text stream that trigger external actions. These aren’t hard-coded rules like "if user says 'weather', call weather API." Instead, the model learns statistically when using a tool reduces uncertainty. If inserting a calculator result makes the next sentence more predictable, the model learns to call the calculator there. It’s self-supervised learning applied to action selection.
| Method | Decision Logic | Training Required? | Flexibility |
|---|---|---|---|
| Hard-coded Rules | If/Then statements | No | Low (brittle) |
| ReAct Prompting | Prompt instructions + Reasoning trace | No | Medium (depends on prompt quality) |
| Toolformer | Learned perplexity reduction | Yes (Fine-tuning) | High (internalized policy) |
| Modern Function Calling | Schema-guided generation | No (usually) | High (structured output) |
The Self-Supervised Training Loop
The magic happens during fine-tuning. You don’t need thousands of human-labeled examples saying "call the calculator here." You give the base model a corpus of text and a set of candidate tools with simple demo prompts. The model generates potential API calls at various points in the text. Then, you actually run those calls. Did the API return useful data? If yes, you replace the original text segment with the API call marker and the result. Crucially, you keep this new sequence only if it lowers the perplexity-meaning the model finds the text easier to predict now that the fact is provided by the tool. This filters out useless calls. The model learns that calling a search engine helps when discussing recent news, but calling a calculator doesn’t help when writing poetry.
From Paper to Production: Modern Function Calling
While Toolformer required fine-tuning weights, today’s APIs from OpenAI, Anthropic, and Google offer similar benefits without retraining. They use "function calling" schemas. You define a tool like `get_weather(location: string)` in JSON. The model sees this schema in the system prompt. When it decides to use the tool, it outputs a structured JSON object instead of plain text. Your code intercepts this, runs the function, and sends the result back. This mimics Toolformer’s behavior but relies on instruction-following capabilities rather than learned token distributions. For most developers in 2026, this is the practical implementation of Toolformer-style logic.
When to Use Which Approach
Don’t over-engineer. If you’re building a chatbot that answers FAQs, simple prompt-based tool use is enough. But if you’re building a financial agent that must execute trades with zero hallucination risk, Toolformer-style fine-tuning offers tighter control. Why? Because the decision to call a tool is baked into the model’s probability distribution, not just following instructions. However, the cost is high. You need GPU resources for fine-tuning and infrastructure to generate and validate millions of candidate API calls. Most startups skip this and stick to robust prompt engineering with strict JSON validation.
Common Pitfalls and How to Fix Them
Even with good models, things break. The biggest issue is "tool overuse." The model gets lazy and calls an API for every question, even trivial ones like "what is 2+2," adding latency and cost. To fix this, add negative examples in your few-shot prompts showing cases where no tool is needed. Another trap is argument hallucination. The model might invent a parameter name that doesn’t exist in your schema. Always enforce strict schema validation in your middleware. If the JSON is malformed, reject it immediately and ask the model to retry, rather than trying to guess what it meant.
Best Practices for Implementation
- Clear Descriptions: Tool descriptions matter more than you think. "Searches web" is bad. "Retrieves real-time stock prices for US equities" is good. Ambiguity leads to wrong tool selection.
- Minimal Arguments: Keep parameter lists short. Complex nested objects confuse models. Flatten your API structures where possible.
- Log Everything: Track which tools are called, with what arguments, and what results come back. Review these logs weekly. You’ll spot patterns, like the model always failing to pass the date format correctly.
- Handle Errors Gracefully: What if the API times out? Don’t let the model crash. Return a clear error message to the LLM so it can apologize or try a different approach.
Frequently Asked Questions
Do I need to fine-tune my model to use Toolformer-style prompts?
Not necessarily. Original Toolformer required fine-tuning. However, modern "function calling" APIs achieve similar results through advanced prompting and instruction tuning already present in base models. You only need fine-tuning if you require highly specialized, low-latency tool decisions that prompt-only methods can't reliably handle.
How does Toolformer differ from ReAct prompting?
ReAct relies on explicit reasoning steps written in text (Thought -> Action -> Observation) guided by prompt templates. Toolformer integrates tool usage into the model's internal token prediction process via fine-tuning. ReAct is easier to implement but can be brittle if prompts drift. Toolformer is more robust but requires significant computational resources for training.
Can Toolformer work with any API?
Yes, provided the API returns text or structured data that can be interpreted by the LLM. The key is defining the input parameters clearly. Whether it's a SQL database query, a Python script execution, or a REST endpoint, the interface must be consistent so the model can learn the pattern.
What is perplexity in the context of Toolformer?
Perplexity measures how surprised the model is by the next token in a sequence. In Toolformer, if inserting an API call result makes the surrounding text less surprising (lower perplexity), the model considers that tool call useful. This metric acts as an automatic filter to discard irrelevant or incorrect tool invocations during training.
Is Toolformer suitable for real-time applications?
The inference speed is comparable to standard LLM generation, but network latency from API calls adds delay. Real-time suitability depends on your specific tools. Fast local tools (calculators, simple lookups) are fine. Slow external services (complex searches, third-party SaaS) may introduce noticeable lag, requiring async handling in your application layer.