Workload Placement: Matching LLM Tasks to Models and Infrastructure
- Mark Chomiczewski
- 13 October 2026
- 0 Comments
You have a massive budget for GPUs. You have a state-of-the-art Large Language Model (LLM). Yet, your inference costs are through the roof, and latency is spiking during peak hours. The problem isn't usually the model itself-it's where you're running it. This is the core of workload placement: the strategic art of matching specific LLM tasks to the right models and the right hardware.
It sounds simple, but it’s a multi-dimensional puzzle. Do you run that small classification task on a cheap CPU or an expensive H100? Does that long-context generation need high-bandwidth memory, or can it survive on standard DDR5? If you get this wrong, you’re either burning cash on idle resources or throttling user experience with slow responses. Let’s break down how to solve this without needing a PhD in operations research.
The Shift from Traditional Deep Learning to LLM Workloads
If you’ve managed clusters before, you might think LLM workloads look like old-school deep learning jobs. They don’t. Research from facilities like the Shanghai AI Laboratory shows that LLM development follows a distinct paradigm. Unlike the mixed bag of CNNs and RNNs we saw in the 2010s, modern LLMs almost universally use the Transformer architecture. This homogeneity creates a unique challenge: uniformity leads to polarization.
In traditional setups, GPU utilization varied widely. In LLM clusters, utilization often spikes to 100% during training or drops to near zero between batches. It’s not a smooth curve; it’s a binary state. This "all-or-nothing" pattern breaks standard scheduling heuristics designed for diverse, variable loads. When every job looks like a massive, memory-hungry transformer, your scheduler needs to know exactly which nodes have the bandwidth to handle them, not just which ones are free.
| Feature | Traditional DL Workloads | LLM Development/Serving |
|---|---|---|
| Architecture Diversity | High (CNN, LSTM, GNN) | Low (Transformer-dominant) |
| GPU Utilization Pattern | Variable, steady streams | Polarized (0% or 100%) |
| Data Transfer Volume | Moderate, localized | Massive, cross-node dependencies |
| Optimization Goal | Throughput per node | Makespan minimization & cost efficiency |
Decoding the Five Stages of LLM Lifecycle
To place workloads correctly, you must understand what stage the model is in. The lifecycle has five distinct phases, each with different infrastructure demands:
- Data Preparation: Heavy I/O, light compute. Great for storage-optimized instances, terrible for GPUs.
- Pretraining: The beast. Requires massive parallelism, high-speed interconnects (NVLink/InfiniBand), and thousands of GPUs working in lockstep.
- Alignment (SFT/RLHF): Smaller data, high quality. Needs flexible memory footprints because batch sizes vary wildly.
- Deployment: Packaging weights. Mostly CPU-bound compression and quantization tasks.
- Serving (Inference): Real-time requests. Low latency is king. Here, you trade off throughput for speed.
A common mistake is treating all these stages as generic "AI jobs." If you schedule a data prep job on a $30/hour GPU instance, you’re wasting money. If you put a pretraining job on a node with slow Ethernet instead of InfiniBand, you’ll bottleneck the entire cluster on data transfer. Matching the task to the infrastructure means recognizing these phase-specific signatures.
Can LLMs Schedule Themselves?
Here’s a twist: Can the LLM help place its own workloads? A recent study evaluated 21 public LLMs on their ability to solve heterogeneous HPC workload mapping problems. They gave the models textual descriptions of nodes (CPU/RAM/GPU specs) and tasks (dependencies/duration) and asked for a schedule.
The results were mixed. All models generated feasible plans, but they struggled with optimization. While strong models could co-locate dependent tasks to minimize data transfer, weaker ones ignored parallelism opportunities, leading to longer completion times (makespan). The probabilistic nature of LLMs means identical prompts sometimes yield different schedules. For now, LLMs are great at explaining *why* a schedule makes sense, but they aren’t reliable enough to be your primary scheduler for complex, constraint-heavy environments. They lack the deterministic guarantees of classical algorithms like Integer Linear Programming (ILP).
Strategic Matching: Small Models vs. Big Iron
Not every task needs a trillion-parameter model. And not every model needs a supercomputer. This is where "model-to-infrastructure" matching saves your budget.
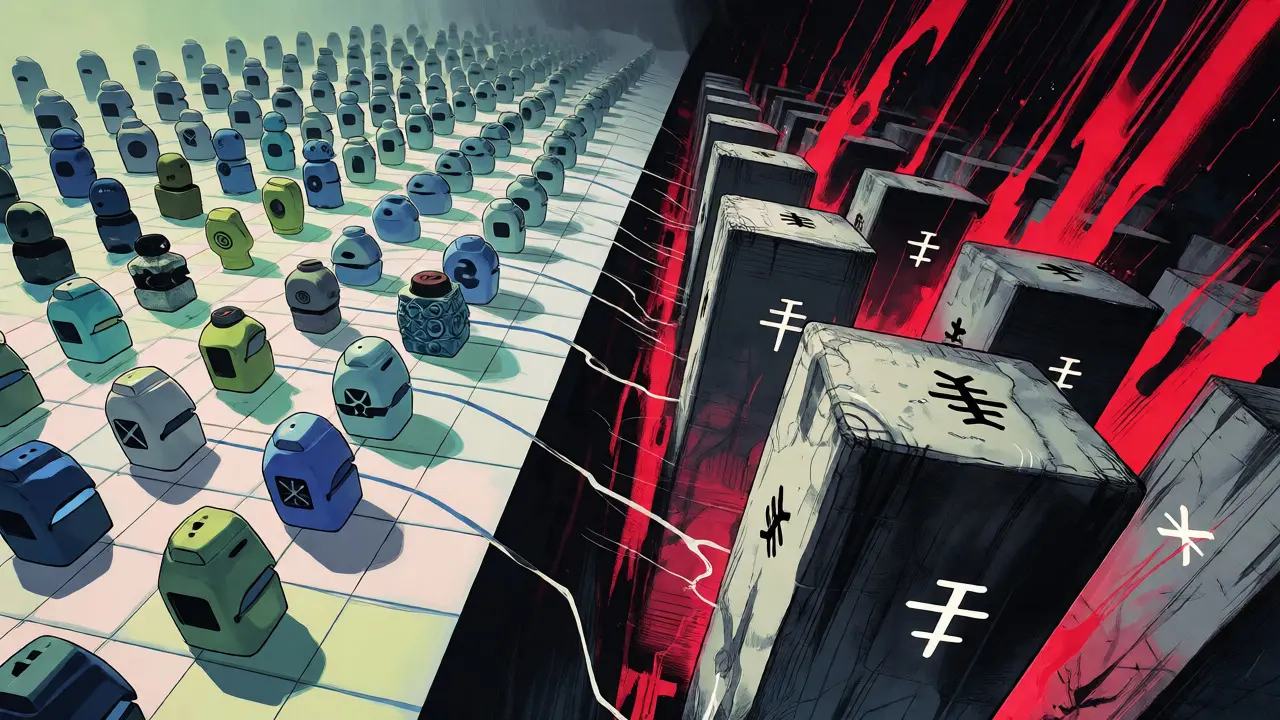
Small Language Models (SLMs) are a game-changer here. With fewer parameters, SLMs can run on edge devices, mobile phones, or modest cloud CPUs. If your task is simple intent classification or short-text summarization, deploying a 7B parameter model on a T4 GPU-or even a CPU-is vastly more efficient than spinning up an A100 for a 70B model.
Conversely, complex reasoning tasks requiring long context windows demand high-bandwidth memory (HBM). Running a large model on consumer-grade VRAM forces you to offload layers to system RAM, which kills inference speed. The rule of thumb: Match the model size to the memory bandwidth of the hardware. Don’t try to squeeze a watermelon into a thimble.
The Cost of Data Gravity
In distributed systems, moving data is expensive. In LLM clusters, it’s catastrophic. Consider a scenario where Task A generates 20GB of output needed by Task B. If Task A runs on Node 1 and Task B runs on Node 2, you pay the network tax twice: once to write, once to read. If the network is congested, your makespan explodes.
Effective workload placement prioritizes data locality. Co-locating dependent tasks on the same node (or rack) reduces transfer overhead. This is why modern schedulers favor "gang scheduling"-allocating groups of nodes together so related tasks stay close. If you ignore this, you might find your GPUs sitting idle, waiting for data to crawl across the network. Always map tasks with heavy inter-dependencies to high-speed local storage or shared memory regions.
Practical Heuristics for Today’s Teams
You don’t need a custom solver to start optimizing. Use these rules of thumb:
- Profile First: Never guess. Run a quick benchmark to see if your task is compute-bound (needs faster clocks) or memory-bound (needs more bandwidth). Most LLM inference is memory-bound.
- Quantize Before Scaling: Before buying bigger GPUs, try quantizing your model (e.g., FP16 to INT8). It often halves memory usage with negligible accuracy loss, allowing you to fit larger models on cheaper hardware.
- Batch Strategically: Dynamic batching increases throughput but hurts latency. For real-time chatbots, keep batches small. For background document processing, go big.
- Separate Training and Serving: Don’t mix interactive inference jobs with long-running training jobs on the same cluster. One needs low latency; the other needs high throughput. They compete for resources differently.
By aligning your infrastructure choices with the specific physical constraints of your LLM tasks, you stop fighting physics and start leveraging it. The goal isn’t just to run the model; it’s to run it efficiently, predictably, and affordably.
What is the biggest mistake in LLM workload placement?
The most common error is assuming all AI workloads are equal. Treating a lightweight inference request with the same resource priority as a massive pretraining job leads to severe resource fragmentation. Another major issue is ignoring data gravity; placing dependent tasks on distant nodes causes significant latency due to network transfer times.
Can LLMs optimize their own infrastructure scheduling?
Currently, LLMs can assist in scheduling by interpreting natural language constraints and proposing feasible mappings. However, they lack the deterministic optimality guarantees of classical algorithms like Mixed-Integer Linear Programming. They are best used as advisory tools rather than primary autonomous schedulers for complex, multi-node environments.
Why do LLM workloads show polarized GPU utilization?
This stems from the homogeneous Transformer architecture used by most modern LLMs. Unlike diverse traditional deep learning models, LLM training involves synchronized, heavy computational steps that saturate GPU memory and compute units completely, followed by brief pauses for data loading or synchronization, resulting in a binary 0% or 100% utilization pattern.
When should I use Small Language Models (SLMs)?
Use SLMs when your task complexity is moderate (e.g., sentiment analysis, short summarization) and latency or cost is critical. SLMs require less memory bandwidth and can run on cheaper hardware or edge devices, offering a better price-performance ratio than large models for straightforward tasks.
How does quantization affect workload placement?
Quantization reduces the precision of model weights (e.g., from 16-bit to 8-bit), significantly lowering memory requirements. This allows larger models to fit on smaller, cheaper GPUs, changing the optimal placement strategy. It shifts the bottleneck from memory capacity to compute capability, potentially making older GPU generations viable for production serving.